构建高效的 AI Agent
Note: Much of the tooling landscape described in this post has changed since December 2024. For our current approach, see how we built Claude Managed Agents and the Managed Agents documentation.
注:这篇文章里提到的工具生态,从 2024 年 12 月到现在已经变了不少。我们现在的做法可以看我们是怎么做 Claude Managed Agents 的和 Managed Agents 文档。
Over the past year, we've worked with dozens of teams building large language model (LLM) agents across industries. Consistently, the most successful implementations weren't using complex frameworks or specialized libraries. Instead, they were building with simple, composable patterns.
过去一年,我们跟各行各业几十个在做大语言模型(LLM)Agent 的团队合作过。一个反复出现的现象是,做得最好的那几家都没用什么复杂的框架或专门的库,用的是简单、可以自由组合的模式。
In this post, we share what we’ve learned from working with our customers and building agents ourselves, and give practical advice for developers on building effective agents.
这篇文章分享的是我们跟客户合作、以及自己动手做 Agent 学到的东西,也给开发者一些构建高效 Agent 的实用建议。
What are agents?什么是 Agent?
"Agent" can be defined in several ways. Some customers define agents as fully autonomous systems that operate independently over extended periods, using various tools to accomplish complex tasks. Others use the term to describe more prescriptive implementations that follow predefined workflows. At Anthropic, we categorize all these variations as agentic systems, but draw an important architectural distinction between workflows and agents:
「Agent」有好几种定义。有的客户说的 Agent 是完全自主的系统,能长时间独立运行,调用各种工具去完成复杂任务;也有人拿这个词指更按部就班的实现,照着预先定好的工作流一步步走。在 Anthropic,这些我们统称为 Agent 系统(agentic systems),但在架构上会把工作流(workflows)和 Agent(agents)明确分开:
- Workflows are systems where LLMs and tools are orchestrated through predefined code paths.工作流:LLM 和工具通过预先写好的代码路径编排起来的系统。
- Agents, on the other hand, are systems where LLMs dynamically direct their own processes and tool usage, maintaining control over how they accomplish tasks.Agent:由 LLM 动态决定自己的流程和工具调用、自己掌控任务怎么完成的系统。
Below, we will explore both types of agentic systems in detail. In Appendix 1 (“Agents in Practice”), we describe two domains where customers have found particular value in using these kinds of systems.
下面会把这两类 Agent 系统分别展开讲。附录 1(「Agent 实践」)介绍了两个领域,客户在这两个领域用这类系统收获特别大。
When (and when not) to use agents什么时候该用 Agent(什么时候不该)
When building applications with LLMs, we recommend finding the simplest solution possible, and only increasing complexity when needed. This might mean not building agentic systems at all. Agentic systems often trade latency and cost for better task performance, and you should consider when this tradeoff makes sense.
用 LLM 做应用,我们的建议是先找最简单的方案,确实需要了再加复杂度。有时候这意味着根本不用做 Agent 系统。Agent 系统通常是拿延迟和成本换更好的任务效果,这笔账什么时候划算,得自己想清楚。
When more complexity is warranted, workflows offer predictability and consistency for well-defined tasks, whereas agents are the better option when flexibility and model-driven decision-making are needed at scale. For many applications, however, optimizing single LLM calls with retrieval and in-context examples is usually enough.
真要上更复杂的方案时,任务定义清楚的,工作流能给你可预测性和一致性;需要大规模的灵活性、需要让模型来做决策的,Agent 更合适。不过对很多应用来说,把单次 LLM 调用配上检索和上下文示例调好,一般就够用了。
When and how to use frameworks什么时候用框架,怎么用
There are many frameworks that make agentic systems easier to implement, including:
能让 Agent 系统更好实现的框架不少,比如:
- The Claude Agent SDK;Claude Agent SDK;
- Strands Agents SDK by AWS;AWS 出的 Strands Agents SDK;
- Rivet, a drag and drop GUI LLM workflow builder; andRivet,拖拽式的 LLM 工作流图形化搭建工具;
- Vellum, another GUI tool for building and testing complex workflows.Vellum,另一个图形化工具,用来搭建和测试复杂的工作流。
These frameworks make it easy to get started by simplifying standard low-level tasks like calling LLMs, defining and parsing tools, and chaining calls together. However, they often create extra layers of abstraction that can obscure the underlying prompts and responses, making them harder to debug. They can also make it tempting to add complexity when a simpler setup would suffice.
这些框架把调用 LLM、定义和解析工具、把多次调用串起来这类底层的标准活儿都包好了,上手很快。问题是它们常常多出几层抽象,把底下真正的提示词和响应挡住,调试起来更费劲。它们还容易让人手痒去加复杂度,哪怕简单的搭法就已经够了。
We suggest that developers start by using LLM APIs directly: many patterns can be implemented in a few lines of code. If you do use a framework, ensure you understand the underlying code. Incorrect assumptions about what's under the hood are a common source of customer error.
我们建议开发者先直接调 LLM API,很多模式几行代码就能写出来。要是用了框架,一定得把底层代码弄懂。对框架内部怎么运作想当然,是客户最常踩的坑之一。
See our cookbook for some sample implementations.
一些示例实现可以看我们的 cookbook。
Building blocks, workflows, and agents基础组件、工作流和 Agent
In this section, we’ll explore the common patterns for agentic systems we’ve seen in production. We'll start with our foundational building block—the augmented LLM—and progressively increase complexity, from simple compositional workflows to autonomous agents.
这一节把我们在生产环境里见过的 Agent 系统常见模式过一遍。先从最基础的组件「增强型 LLM」讲起,再一步步加复杂度,从简单的组合式工作流一直讲到自主 Agent。
Building block: The augmented LLM基础组件:增强型 LLM
The basic building block of agentic systems is an LLM enhanced with augmentations such as retrieval, tools, and memory. Our current models can actively use these capabilities—generating their own search queries, selecting appropriate tools, and determining what information to retain.
Agent 系统最基本的组件,是一个加上了检索、工具、记忆这些增强能力的 LLM。我们现在的模型能主动用这些能力:自己生成搜索词,自己挑合适的工具,自己决定哪些信息要记住。
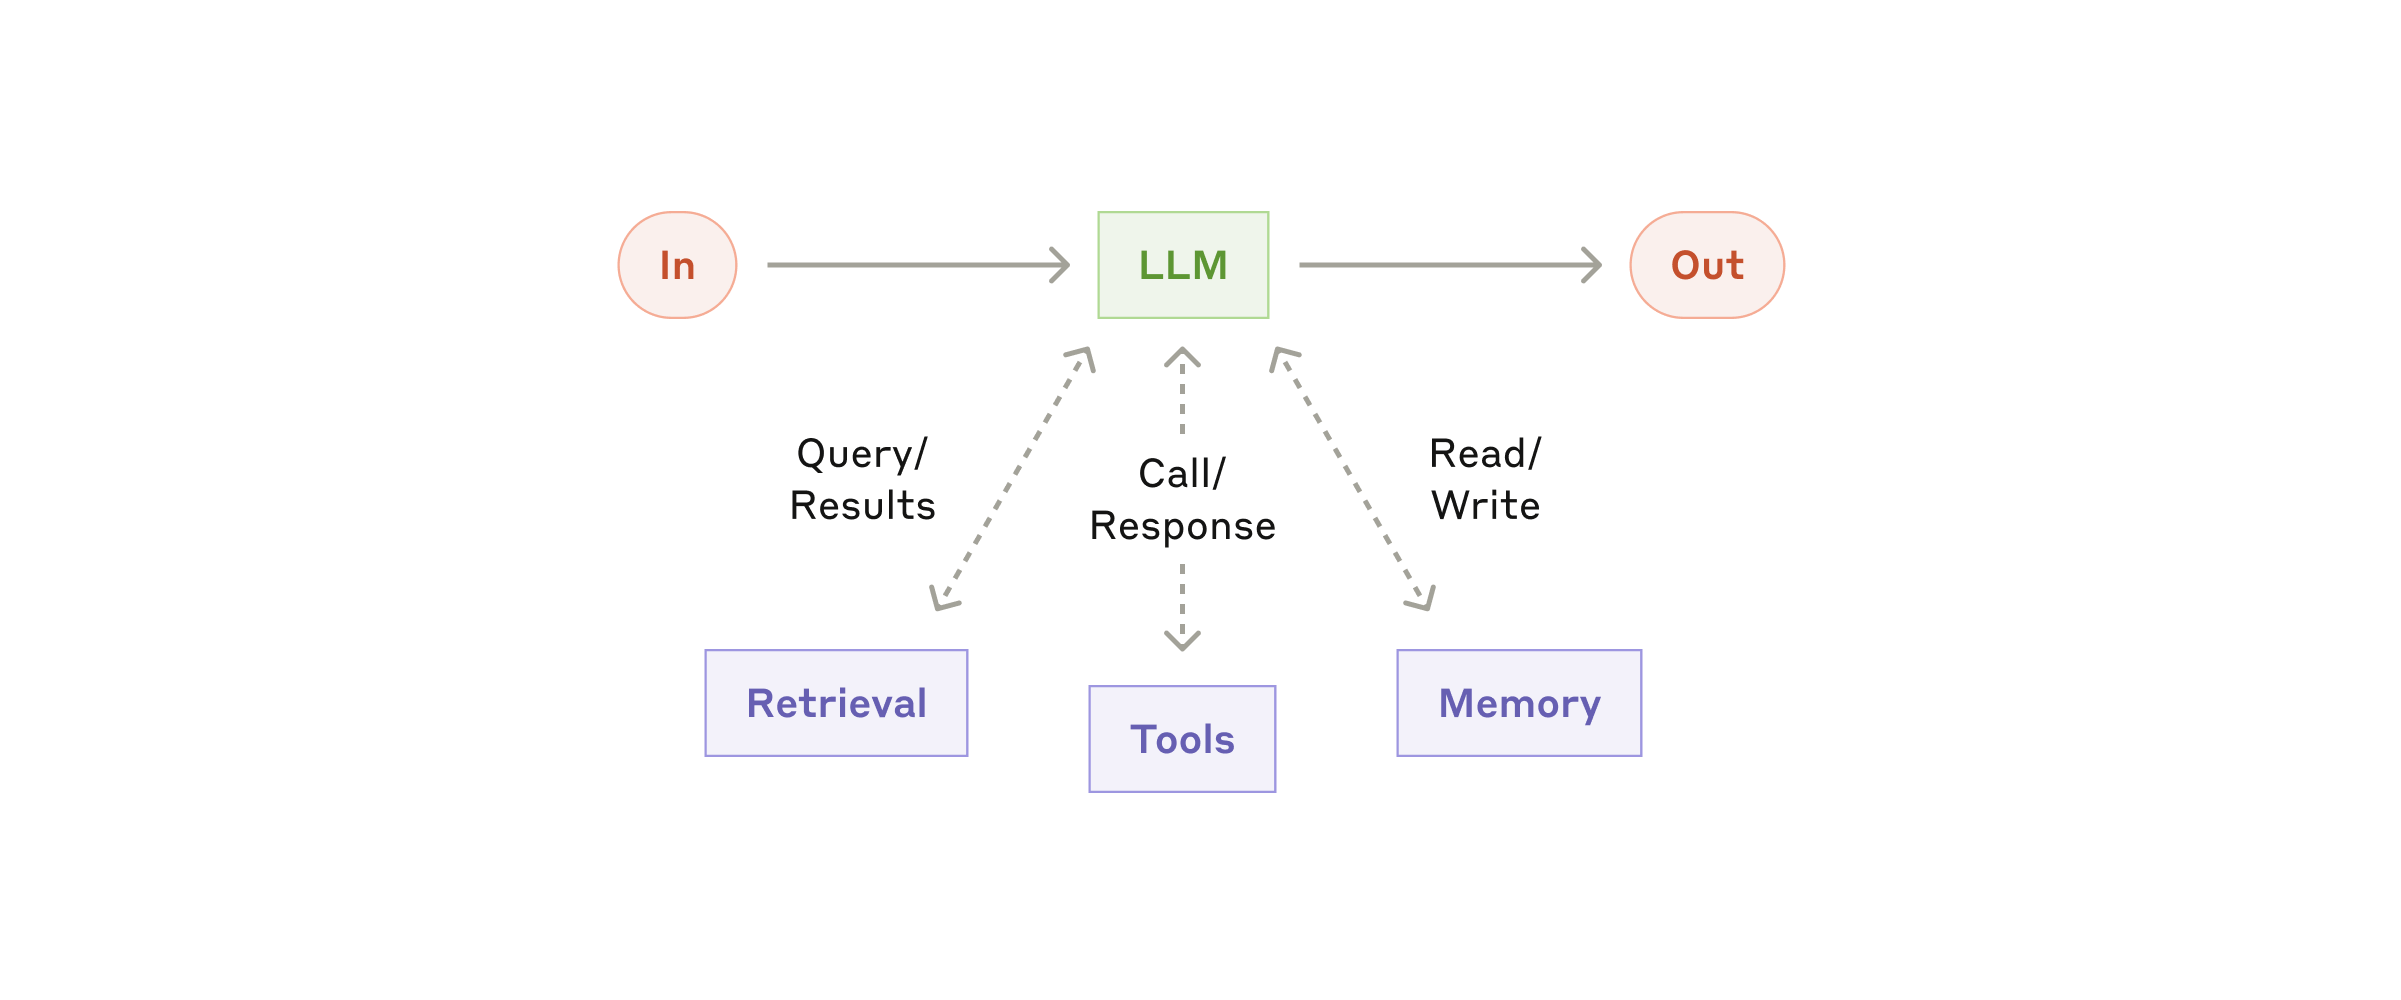
The augmented LLM
增强型 LLM
We recommend focusing on two key aspects of the implementation: tailoring these capabilities to your specific use case and ensuring they provide an easy, well-documented interface for your LLM. While there are many ways to implement these augmentations, one approach is through our recently released Model Context Protocol, which allows developers to integrate with a growing ecosystem of third-party tools with a simple client implementation.
实现时我们建议抓住两点:一是让这些能力贴合你的具体场景,二是给 LLM 提供一个简单好用、文档齐全的接口。实现这些增强能力的办法很多,其中一种是用我们最近发布的 Model Context Protocol,开发者只要写一个简单的客户端,就能接入越来越多的第三方工具。
For the remainder of this post, we'll assume each LLM call has access to these augmented capabilities.
本文后面都默认每次 LLM 调用都能用上这些增强能力。
Workflow: Prompt chaining工作流:提示词链
Prompt chaining decomposes a task into a sequence of steps, where each LLM call processes the output of the previous one. You can add programmatic checks (see "gate” in the diagram below) on any intermediate steps to ensure that the process is still on track.
提示词链(prompt chaining)把一个任务拆成一串步骤,每次 LLM 调用处理上一步的输出。任何一个中间步骤上都可以加程序化的检查(下图里的「gate」),确保流程没跑偏。
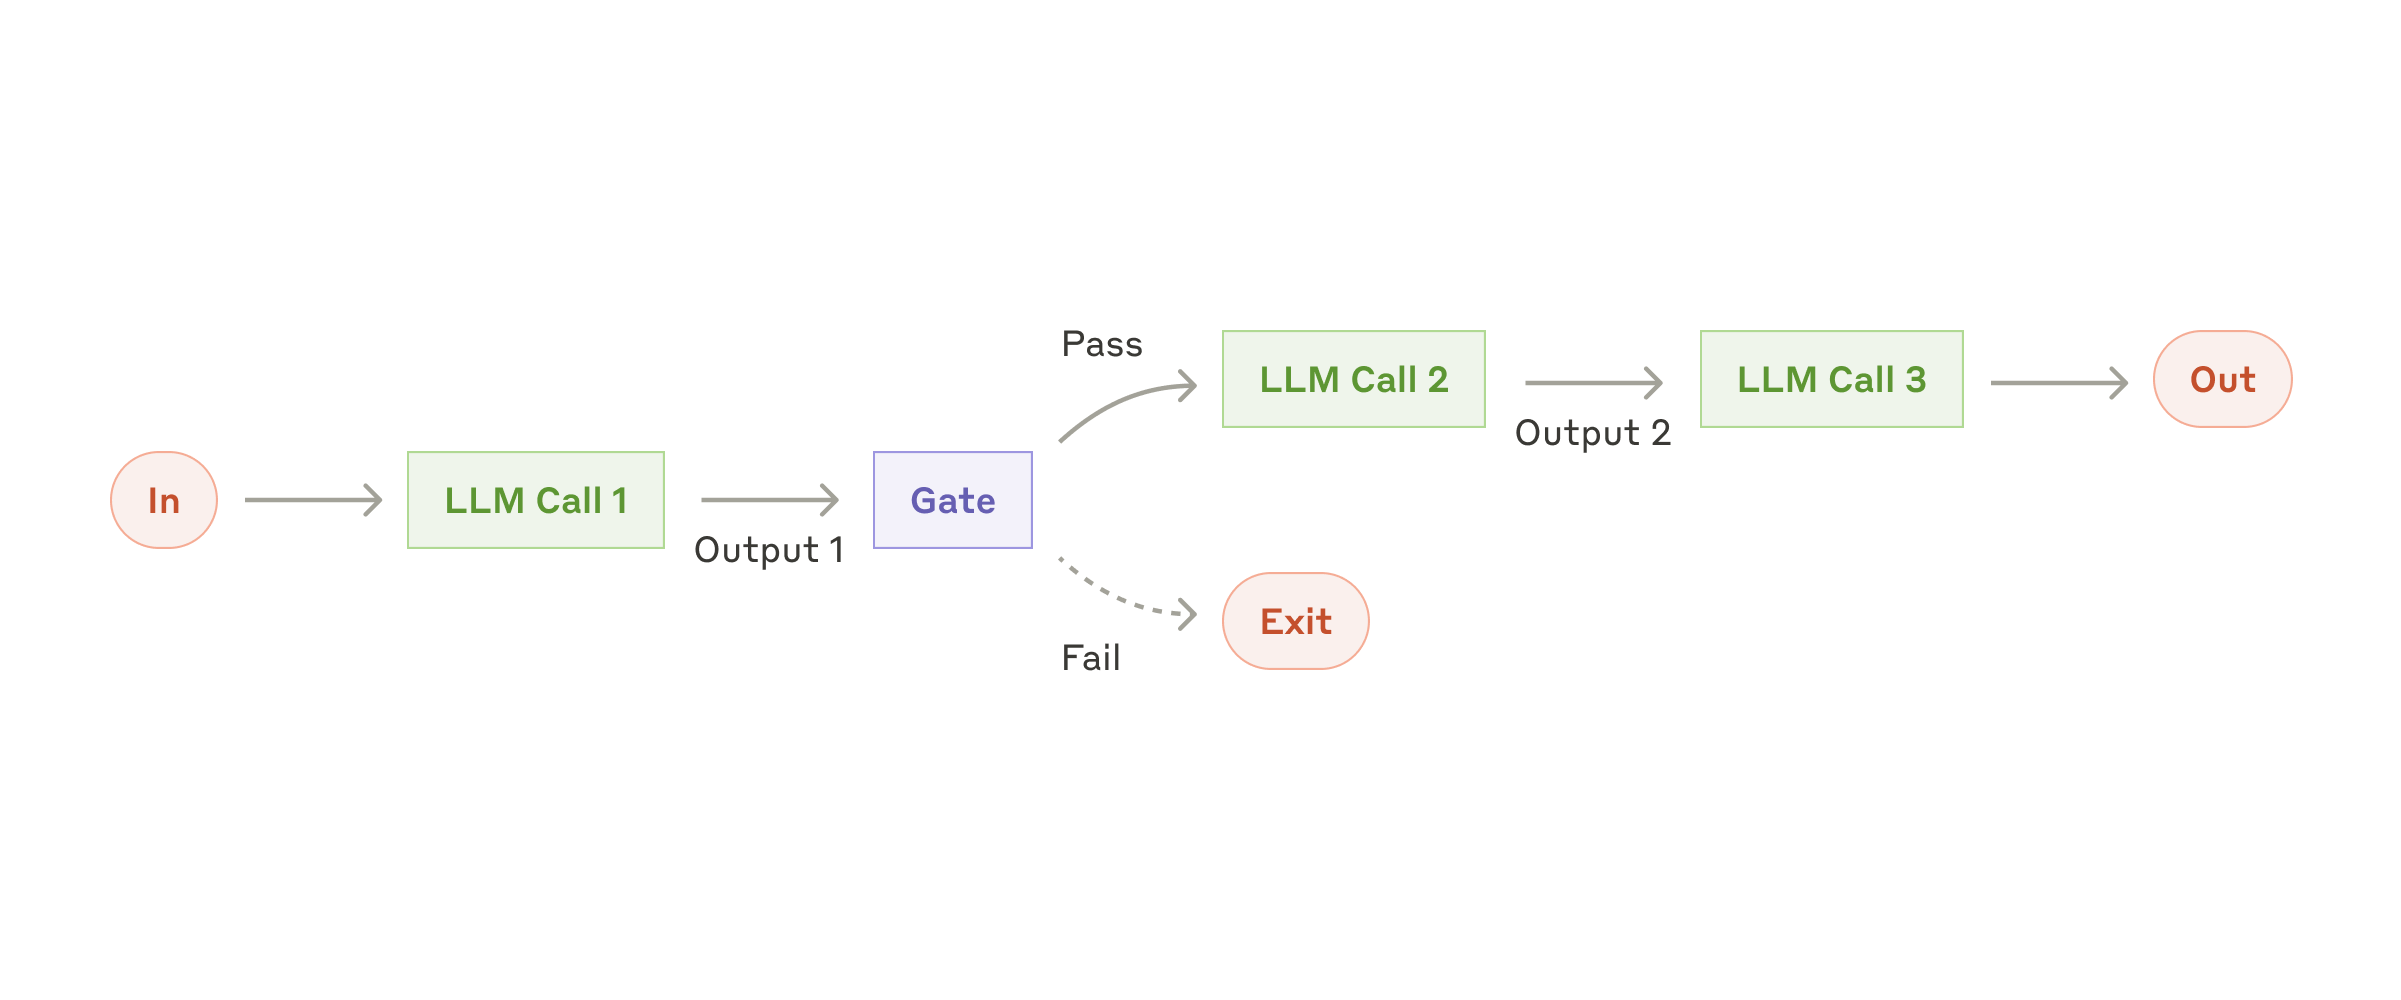
The prompt chaining workflow
提示词链工作流
When to use this workflow: This workflow is ideal for situations where the task can be easily and cleanly decomposed into fixed subtasks. The main goal is to trade off latency for higher accuracy, by making each LLM call an easier task.
适用场景:任务能简单、干净地拆成几个固定子任务时,用这个最合适。说白了就是拿延迟换准确率,让每次 LLM 调用只干一件更简单的事。
Examples where prompt chaining is useful:
提示词链适用的例子:
- Generating Marketing copy, then translating it into a different language.先写营销文案,再翻译成另一种语言。
- Writing an outline of a document, checking that the outline meets certain criteria, then writing the document based on the outline.先写文档大纲,检查大纲是否满足某些标准,再照着大纲把文档写出来。
Workflow: Routing工作流:路由
Routing classifies an input and directs it to a specialized followup task. This workflow allows for separation of concerns, and building more specialized prompts. Without this workflow, optimizing for one kind of input can hurt performance on other inputs.
路由(routing)先给输入分类,再把它交给专门的后续任务。这样能把关注点分开,各自写更有针对性的提示词。不这么做的话,为某一类输入做的优化,可能会拖累其他输入的效果。
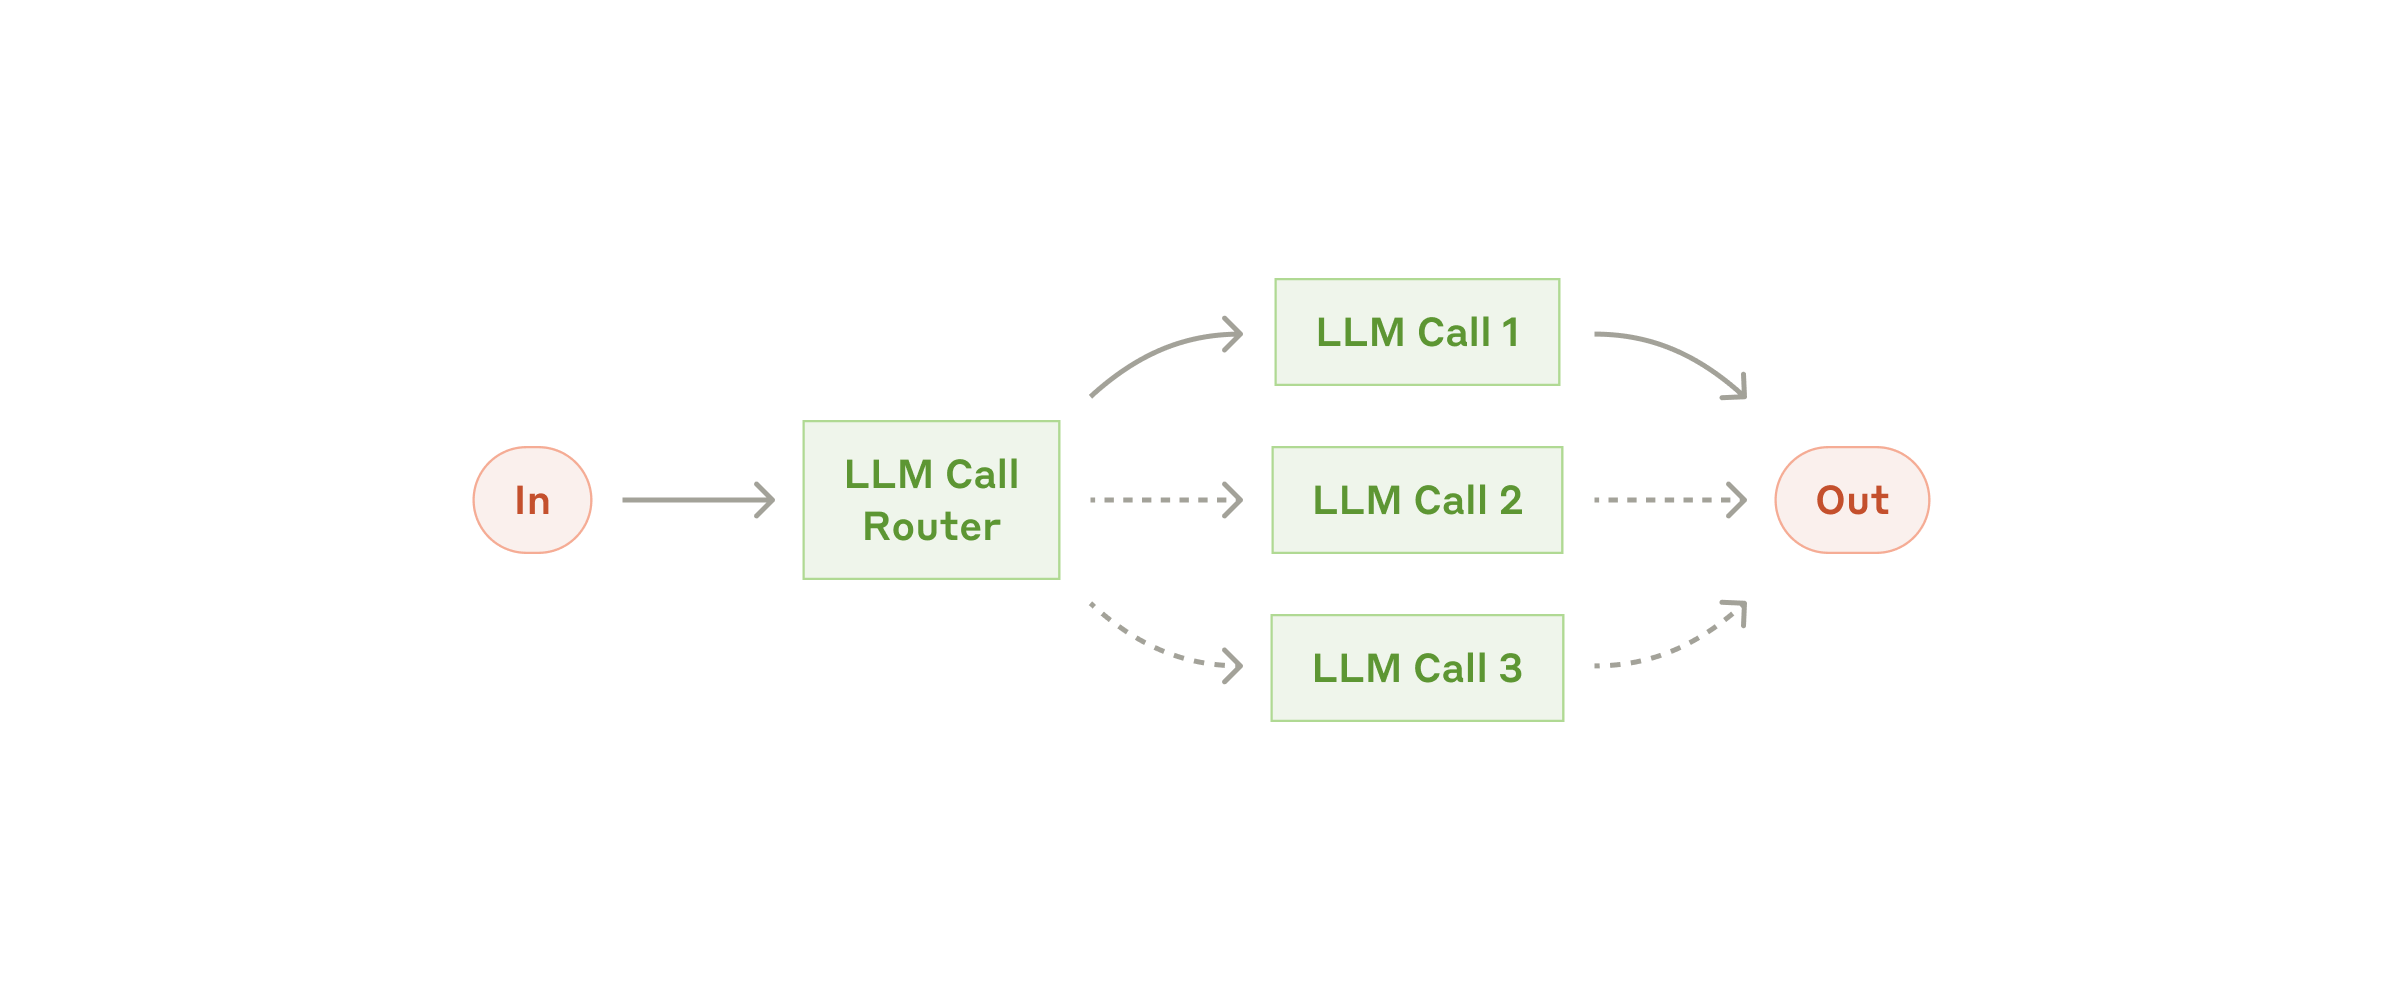
The routing workflow
路由工作流
When to use this workflow: Routing works well for complex tasks where there are distinct categories that are better handled separately, and where classification can be handled accurately, either by an LLM or a more traditional classification model/algorithm.
适用场景:复杂任务里有几类明显不同、分开处理效果更好的情况,而且分类能做准(不管是用 LLM,还是用更传统的分类模型或算法),这时候路由很好用。
Examples where routing is useful:
路由适用的例子:
- Directing different types of customer service queries (general questions, refund requests, technical support) into different downstream processes, prompts, and tools.把不同类型的客服咨询(一般问题、退款申请、技术支持)分到不同的下游流程、提示词和工具。
- Routing easy/common questions to smaller, cost-efficient models like Claude Haiku 4.5 and hard/unusual questions to more capable models like Claude Sonnet 4.5 to optimize for best performance.简单、常见的问题交给 Claude Haiku 4.5 这种更小更省钱的模型,难的、少见的问题交给 Claude Sonnet 4.5 这种能力更强的模型,让整体效果最好。
Workflow: Parallelization工作流:并行化
LLMs can sometimes work simultaneously on a task and have their outputs aggregated programmatically. This workflow, parallelization, manifests in two key variations:
有时候可以让多个 LLM 同时处理一个任务,再用程序把输出汇总起来。这种工作流叫并行化(parallelization),主要有两种形式:
- Sectioning: Breaking a task into independent subtasks run in parallel.分块(Sectioning):把任务拆成互不依赖的子任务,并行跑。
- Voting: Running the same task multiple times to get diverse outputs.投票(Voting):同一个任务跑好几遍,拿到多样的输出。
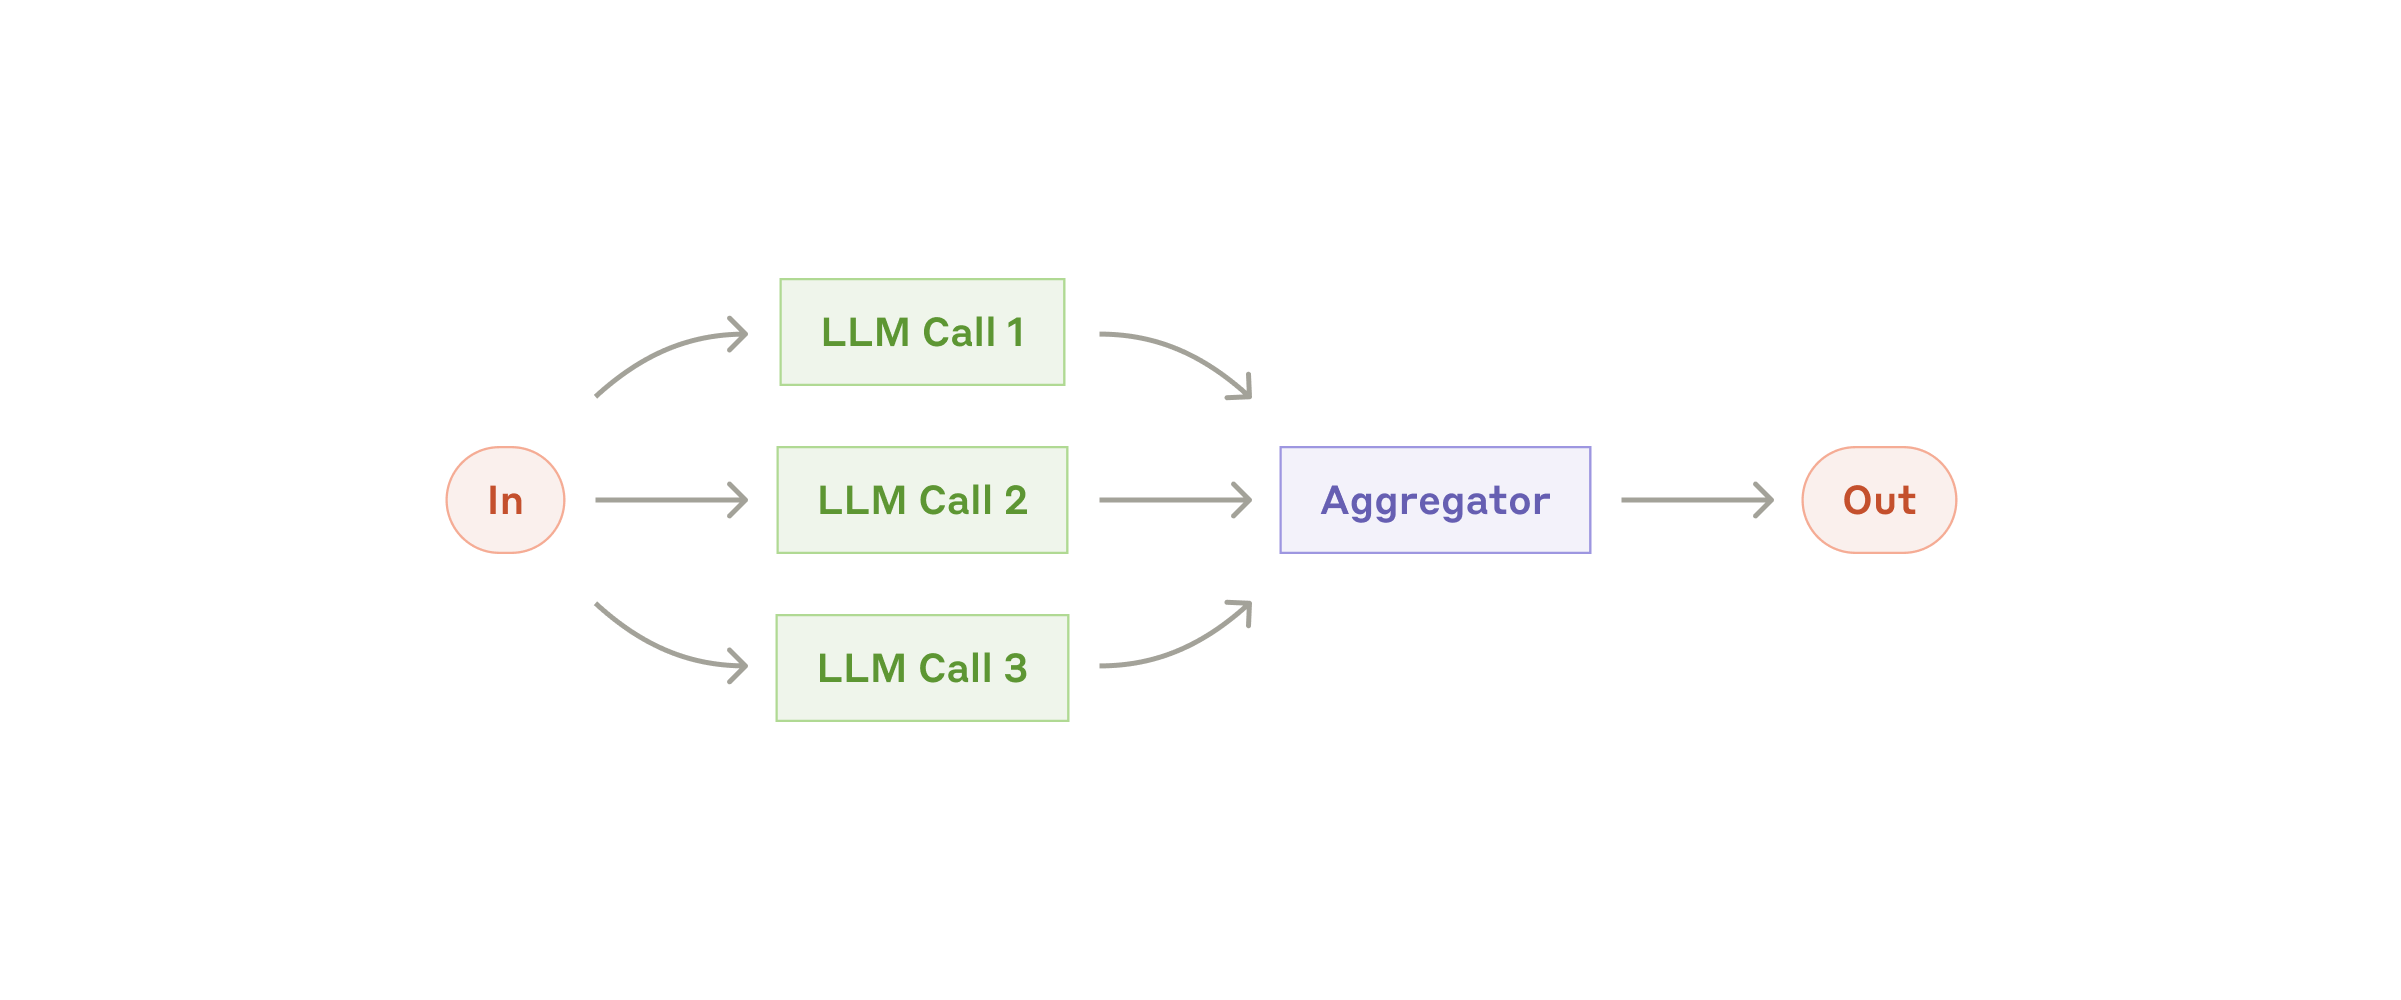
The parallelization workflow
并行化工作流
When to use this workflow: Parallelization is effective when the divided subtasks can be parallelized for speed, or when multiple perspectives or attempts are needed for higher confidence results. For complex tasks with multiple considerations, LLMs generally perform better when each consideration is handled by a separate LLM call, allowing focused attention on each specific aspect.
适用场景:拆出来的子任务能并行跑来提速,或者需要多个角度、多次尝试来让结果更可靠时,并行化很有效。要兼顾好几个方面的复杂任务,让每个方面各用一次单独的 LLM 调用来处理,效果通常更好,因为每次调用都能专心盯着一个具体方面。
Examples where parallelization is useful:
并行化适用的例子:
- Sectioning:分块:
- Implementing guardrails where one model instance processes user queries while another screens them for inappropriate content or requests. This tends to perform better than having the same LLM call handle both guardrails and the core response.做护栏(guardrails):一个模型实例处理用户请求,另一个负责筛查里面有没有不当内容或请求。这通常比让同一次 LLM 调用既管护栏又管正经回答效果更好。
- Automating evals for evaluating LLM performance, where each LLM call evaluates a different aspect of the model’s performance on a given prompt.自动化评测(evals)LLM 的表现:每次 LLM 调用负责评估模型在给定提示词上某一个方面的表现。
- Voting:投票:
- Reviewing a piece of code for vulnerabilities, where several different prompts review and flag the code if they find a problem.审查一段代码有没有漏洞:用几个不同的提示词分别审,谁发现问题谁就标出来。
- Evaluating whether a given piece of content is inappropriate, with multiple prompts evaluating different aspects or requiring different vote thresholds to balance false positives and negatives.判断一段内容是否不当:用多个提示词分别评估不同方面,或者设不同的投票阈值,在误报和漏报之间找平衡。
Workflow: Orchestrator-workers工作流:编排者-工作者
In the orchestrator-workers workflow, a central LLM dynamically breaks down tasks, delegates them to worker LLMs, and synthesizes their results.
在编排者-工作者(orchestrator-workers)工作流里,一个中心 LLM 动态地拆解任务,分派给几个工作者 LLM,最后把它们的结果汇总起来。
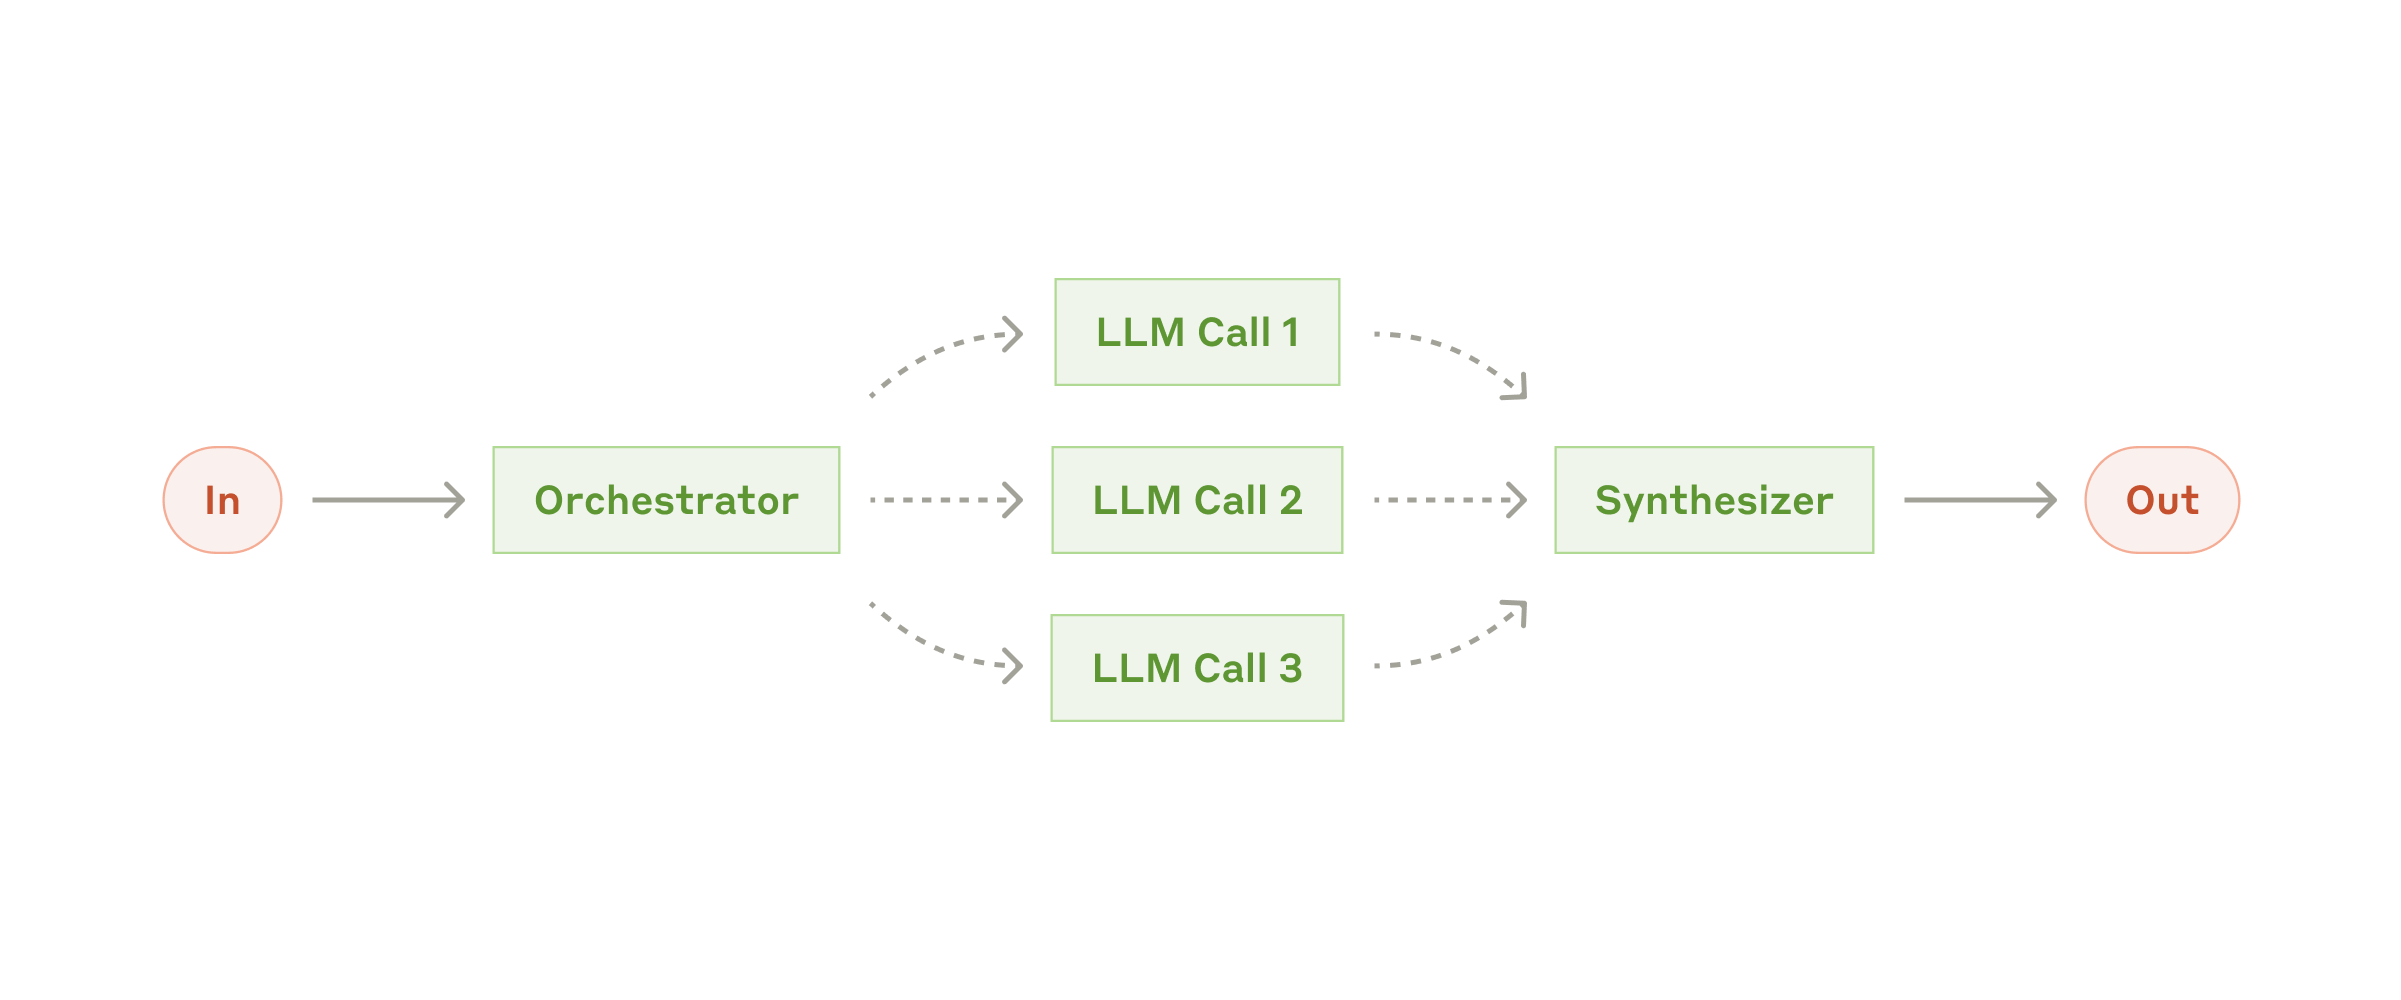
The orchestrator-workers workflow
编排者-工作者工作流
When to use this workflow: This workflow is well-suited for complex tasks where you can’t predict the subtasks needed (in coding, for example, the number of files that need to be changed and the nature of the change in each file likely depend on the task). Whereas it’s topographically similar, the key difference from parallelization is its flexibility—subtasks aren't pre-defined, but determined by the orchestrator based on the specific input.
适用场景:适合事先没法预知需要哪些子任务的复杂任务(比如写代码,要改几个文件、每个文件怎么改,很可能都看具体任务)。它在结构上跟并行化很像,关键区别是更灵活:子任务不是提前定好的,是编排者根据具体输入现场决定的。
Example where orchestrator-workers is useful:
编排者-工作者适用的例子:
- Coding products that make complex changes to multiple files each time.每次都要对多个文件做复杂改动的编程产品。
- Search tasks that involve gathering and analyzing information from multiple sources for possible relevant information.需要从多个来源收集、分析可能相关信息的搜索任务。
Workflow: Evaluator-optimizer工作流:评估者-优化者
In the evaluator-optimizer workflow, one LLM call generates a response while another provides evaluation and feedback in a loop.
在评估者-优化者(evaluator-optimizer)工作流里,一次 LLM 调用负责生成回答,另一次负责评估、给反馈,两边循环往复。
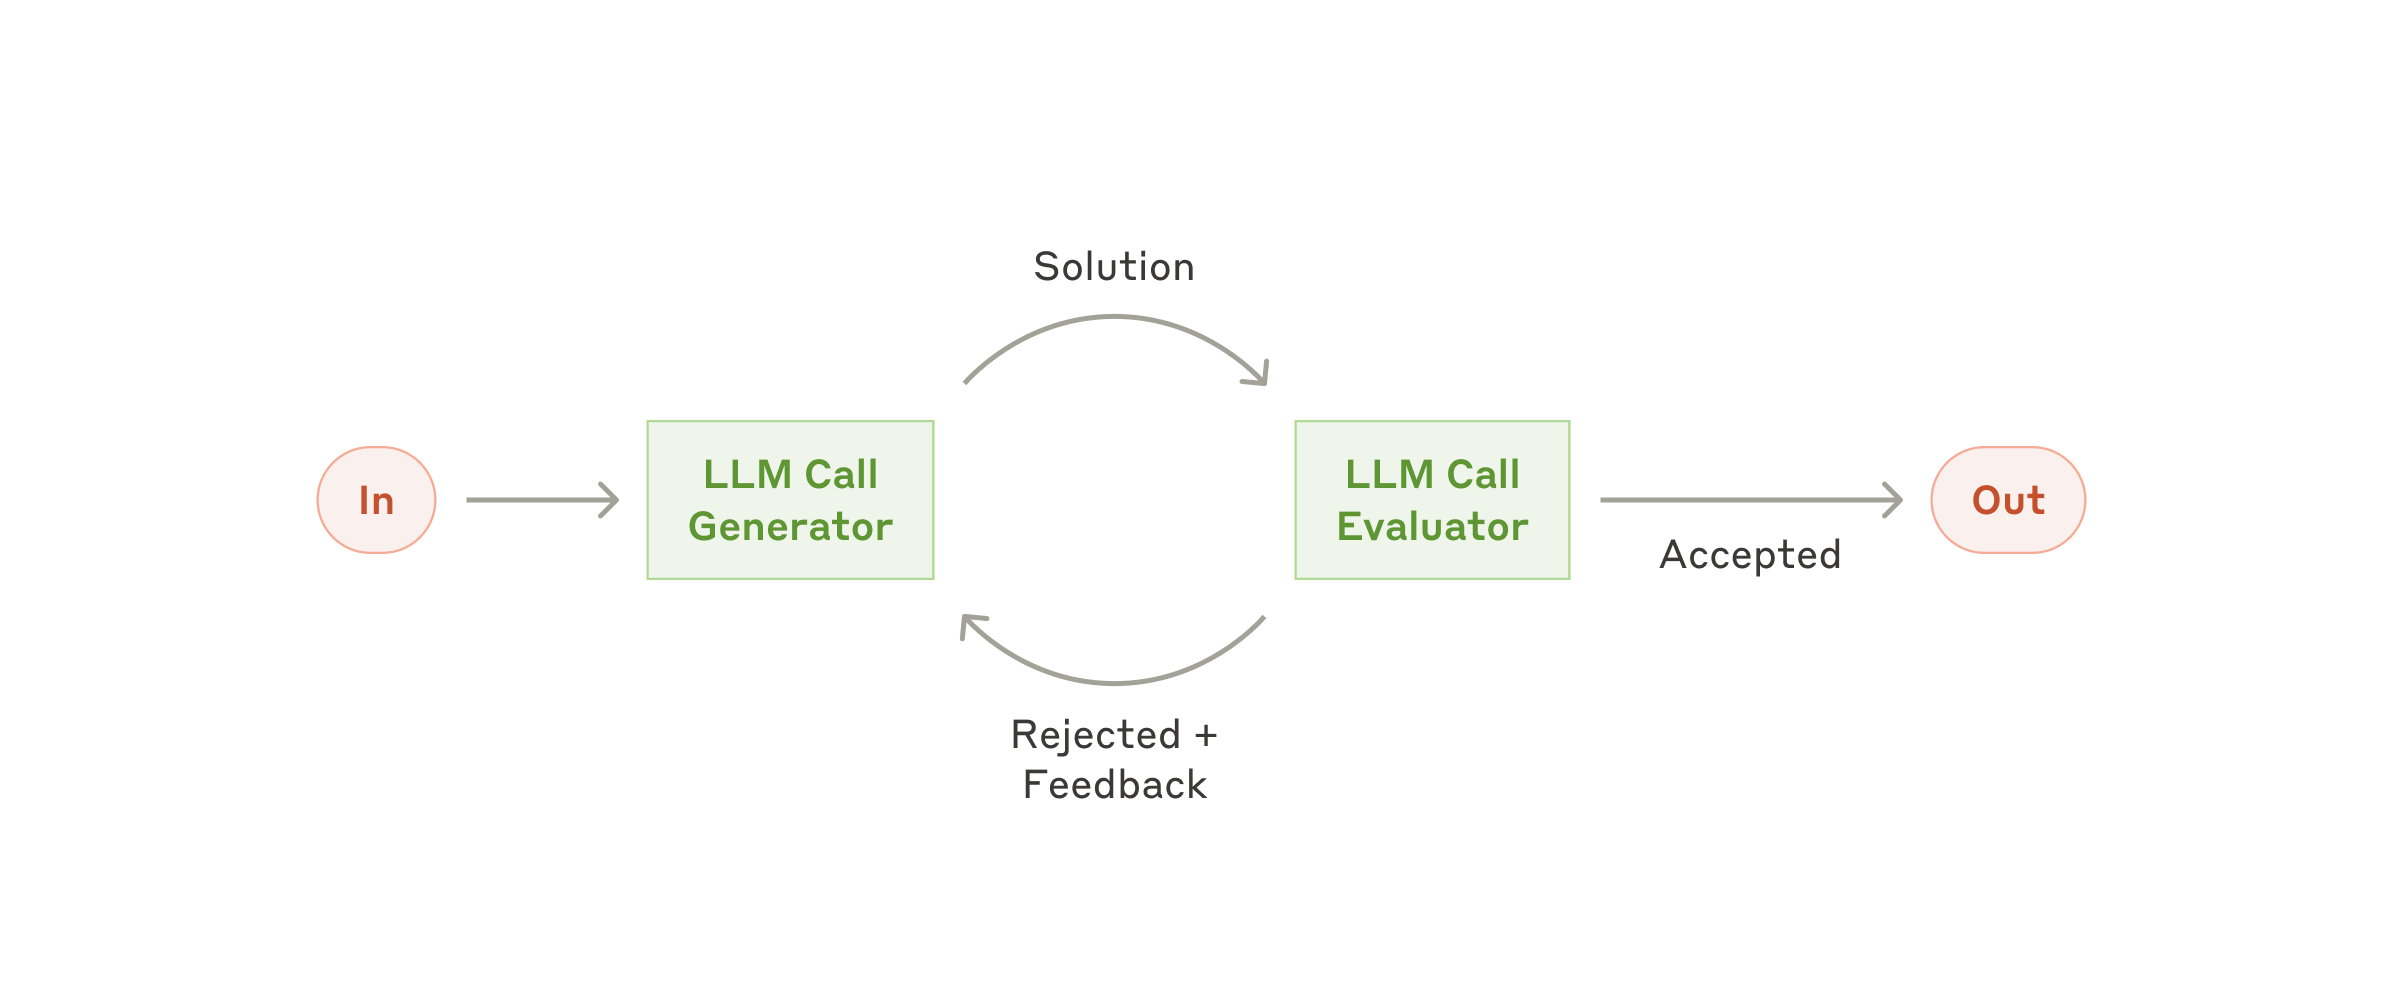
The evaluator-optimizer workflow
评估者-优化者工作流
When to use this workflow: This workflow is particularly effective when we have clear evaluation criteria, and when iterative refinement provides measurable value. The two signs of good fit are, first, that LLM responses can be demonstrably improved when a human articulates their feedback; and second, that the LLM can provide such feedback. This is analogous to the iterative writing process a human writer might go through when producing a polished document.
适用场景:评估标准清楚、反复打磨能带来看得见的提升时,这个工作流特别好用。合不合适看两个信号:第一,人把反馈讲清楚之后,LLM 的回答能明显变好;第二,LLM 自己也能给出这样的反馈。这跟人写东西时一遍遍修改、直到成稿的过程很像。
Examples where evaluator-optimizer is useful:
评估者-优化者适用的例子:
- Literary translation where there are nuances that the translator LLM might not capture initially, but where an evaluator LLM can provide useful critiques.文学翻译:有些细微之处,负责翻译的 LLM 一开始可能抓不住,但负责评估的 LLM 能给出有用的意见。
- Complex search tasks that require multiple rounds of searching and analysis to gather comprehensive information, where the evaluator decides whether further searches are warranted.复杂的搜索任务:要搜好几轮、分析好几轮才能把信息收集全,由评估者判断还要不要继续搜。
AgentsAgent
Agents are emerging in production as LLMs mature in key capabilities—understanding complex inputs, engaging in reasoning and planning, using tools reliably, and recovering from errors. Agents begin their work with either a command from, or interactive discussion with, the human user. Once the task is clear, agents plan and operate independently, potentially returning to the human for further information or judgement. During execution, it's crucial for the agents to gain “ground truth” from the environment at each step (such as tool call results or code execution) to assess its progress. Agents can then pause for human feedback at checkpoints or when encountering blockers. The task often terminates upon completion, but it’s also common to include stopping conditions (such as a maximum number of iterations) to maintain control.
随着 LLM 在几项关键能力上成熟起来(理解复杂输入、推理和规划、可靠地使用工具、从错误中恢复),Agent 开始出现在生产环境里。Agent 开工的起点,要么是用户的一条指令,要么是跟用户的一番来回讨论。任务一旦明确,Agent 就自己规划、独立执行,中途可能回头找人要更多信息或者让人拿主意。执行过程中,Agent 每一步都要从环境里拿到「真实情况(ground truth)」,比如工具调用的结果或者代码的运行结果,用来判断自己进展如何。在检查点上,或者卡住的时候,它可以停下来等人给反馈。任务一般做完就结束,但也常会加上停止条件(比如最大迭代次数),保证事情在掌控之中。
Agents can handle sophisticated tasks, but their implementation is often straightforward. They are typically just LLMs using tools based on environmental feedback in a loop. It is therefore crucial to design toolsets and their documentation clearly and thoughtfully. We expand on best practices for tool development in Appendix 2 ("Prompt Engineering your Tools").
Agent 能处理很复杂的任务,实现起来却往往很直白:通常就是 LLM 在一个循环里,根据环境反馈去调用工具。所以工具集和工具文档设计得清不清楚、周不周到,就特别关键。工具开发的最佳实践,我们在附录 2(「为工具做提示词工程」)里展开讲。
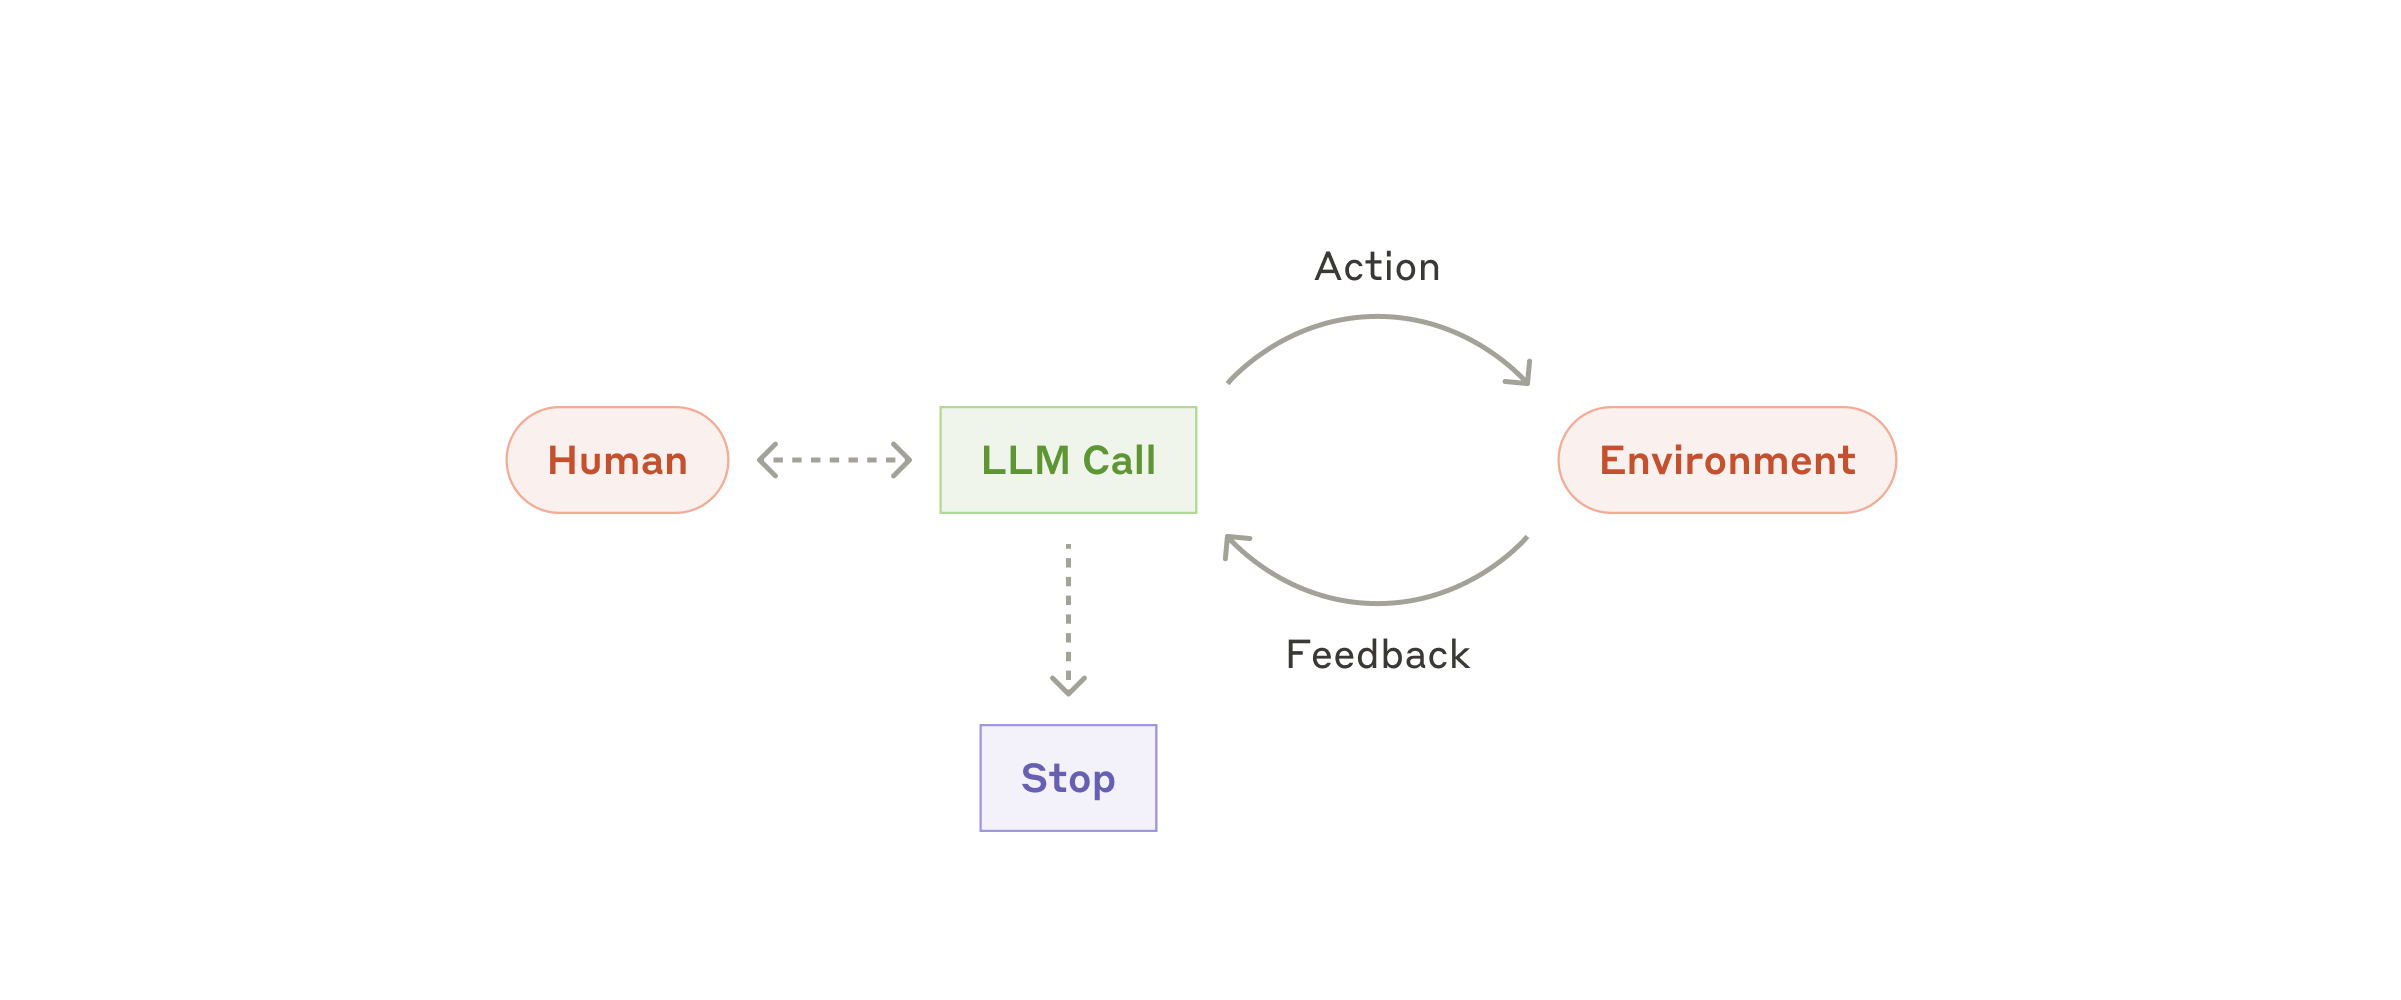
Autonomous agent
自主 Agent
When to use agents: Agents can be used for open-ended problems where it’s difficult or impossible to predict the required number of steps, and where you can’t hardcode a fixed path. The LLM will potentially operate for many turns, and you must have some level of trust in its decision-making. Agents' autonomy makes them ideal for scaling tasks in trusted environments.
适用场景:Agent 适合开放式的问题:需要多少步很难预测甚至根本没法预测,也没法写死一条固定路径。LLM 可能要跑很多轮,你得对它的决策有一定的信任。因为能自主行动,在可信的环境里,Agent 很适合拿来大规模地跑任务。
The autonomous nature of agents means higher costs, and the potential for compounding errors. We recommend extensive testing in sandboxed environments, along with the appropriate guardrails.
自主也意味着成本更高,错误还可能越滚越大。我们建议先在沙箱环境里充分测试,再配上合适的护栏。
Examples where agents are useful:
Agent 适用的例子:
The following examples are from our own implementations:
下面这些例子来自我们自己的实现:
- A coding Agent to resolve SWE-bench tasks, which involve edits to many files based on a task description;一个解决 SWE-bench 任务的编程 Agent,这些任务要根据一段任务描述去改很多文件;
- Our “computer use” reference implementation, where Claude uses a computer to accomplish tasks.我们的「computer use」参考实现,Claude 在里面操作电脑来完成任务。
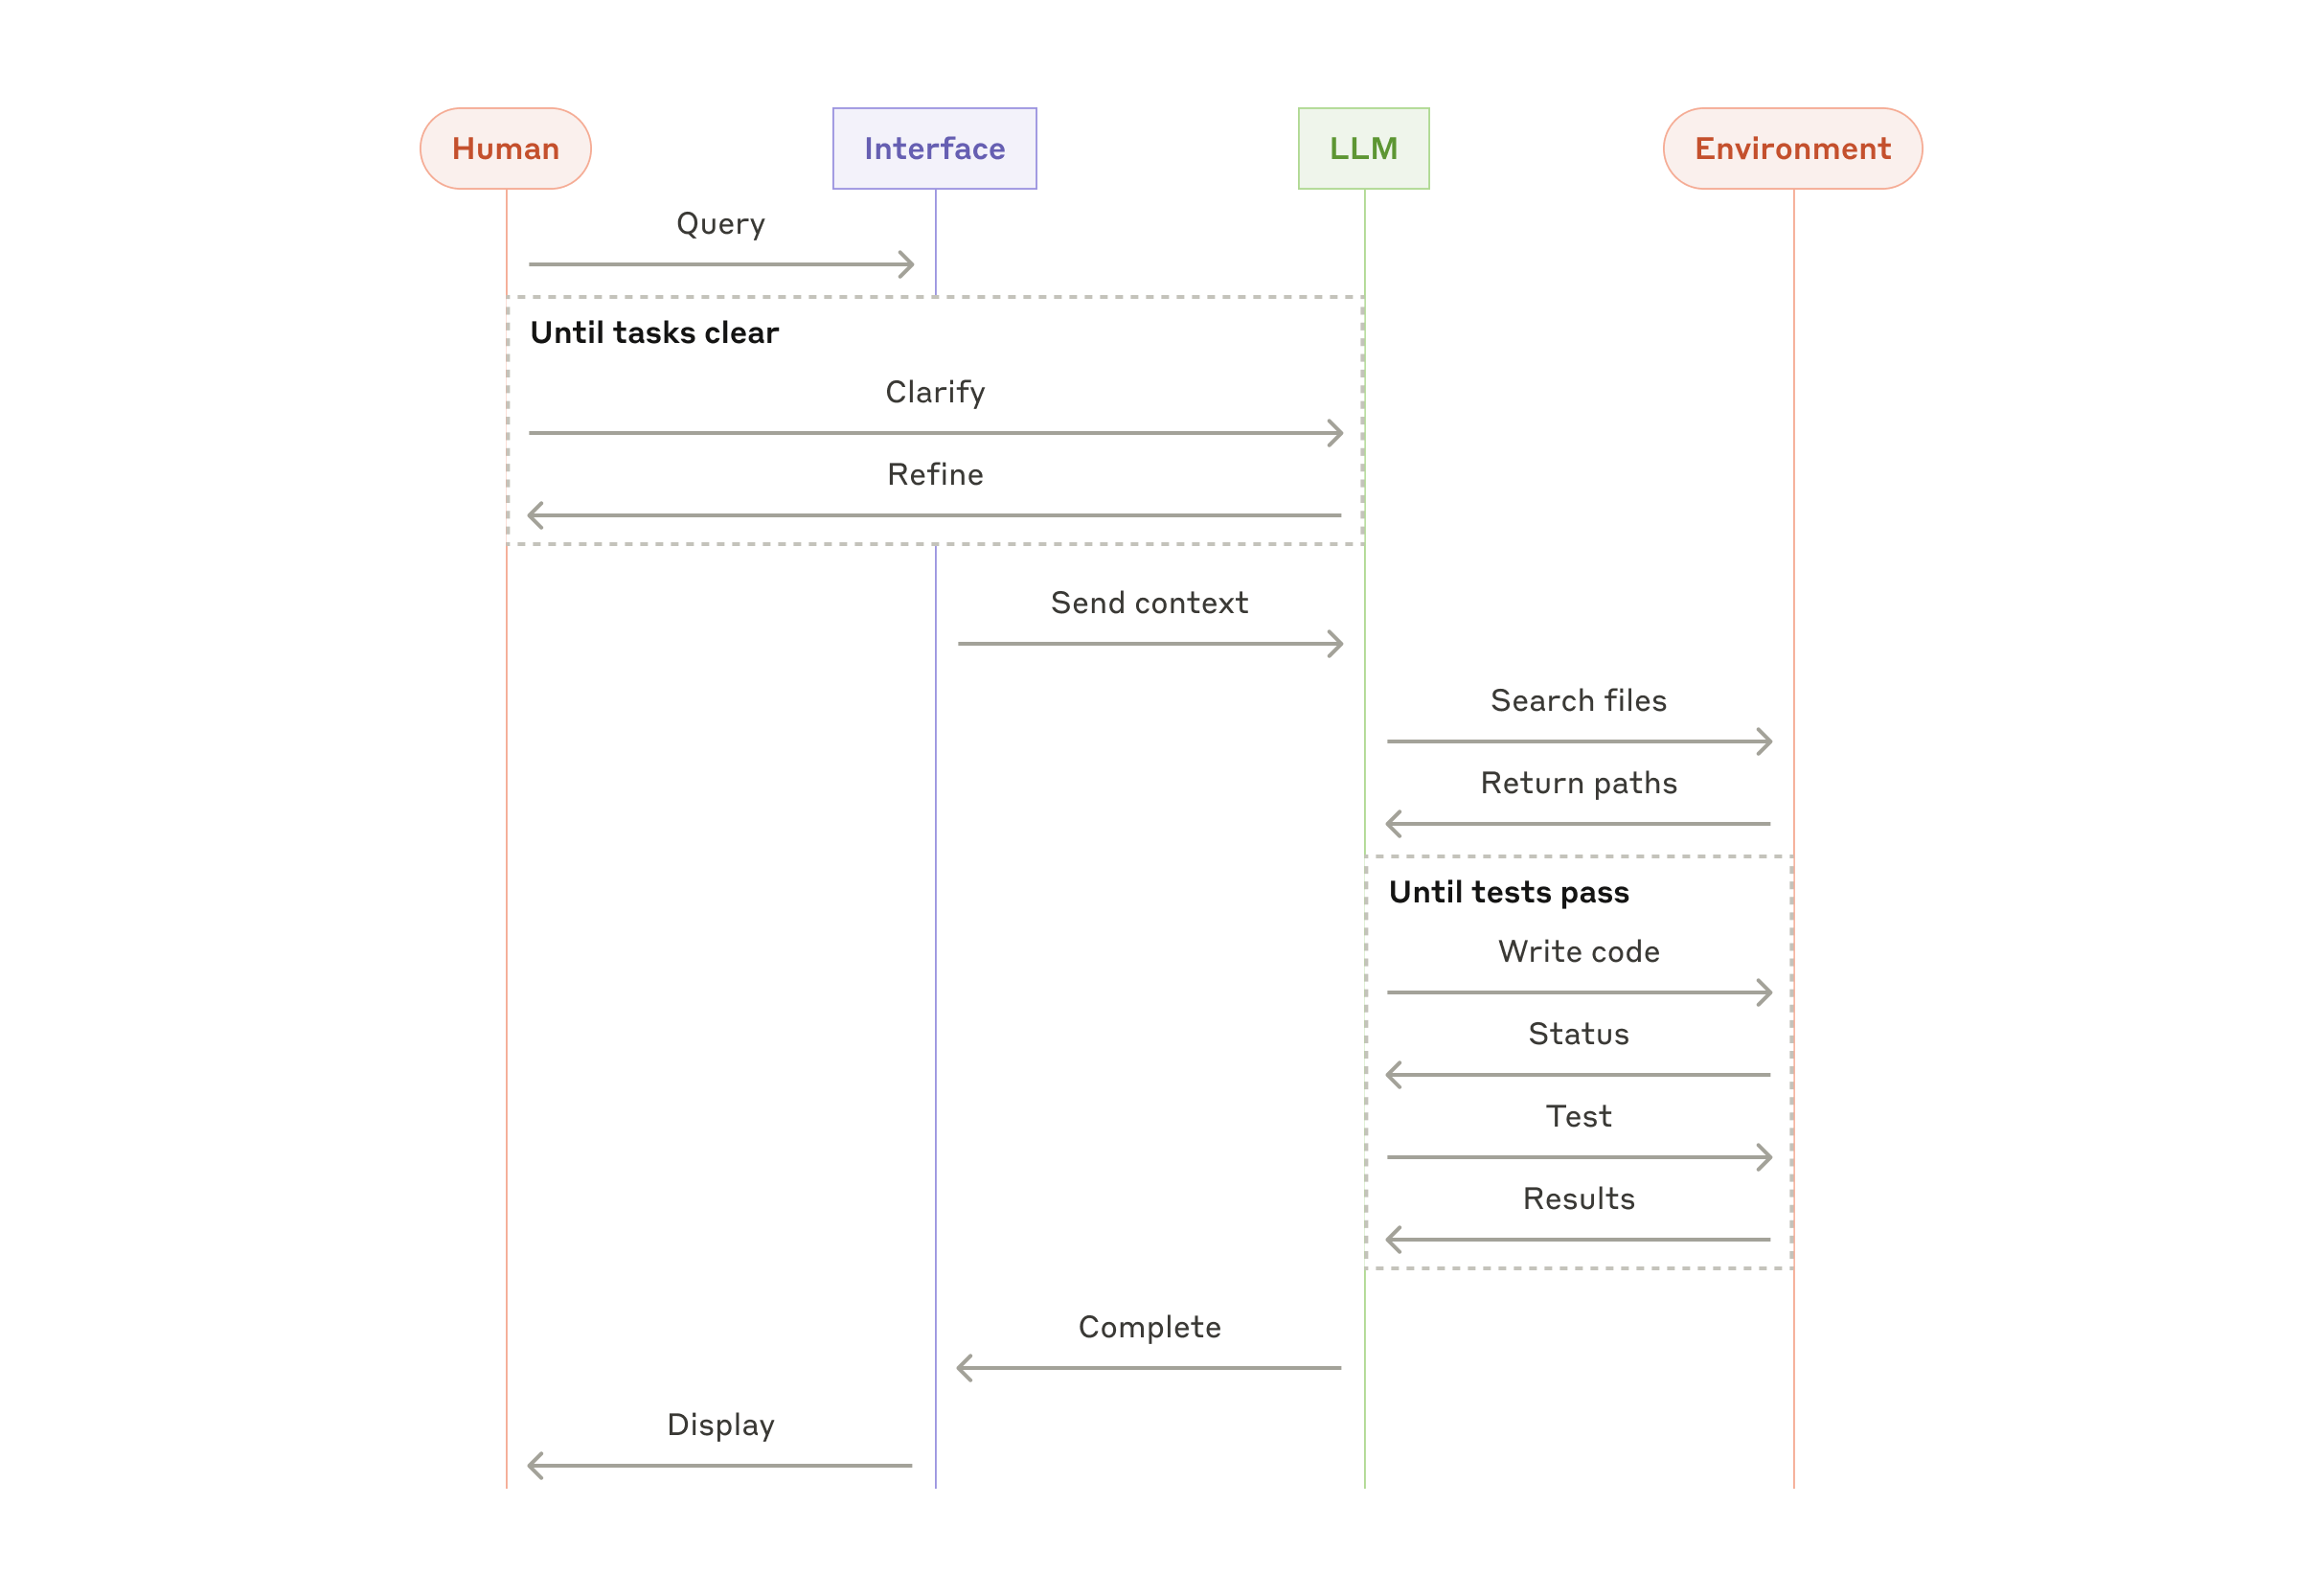
High-level flow of a coding agent
编程 Agent 的总体流程
Combining and customizing these patterns组合和定制这些模式
These building blocks aren't prescriptive. They're common patterns that developers can shape and combine to fit different use cases. The key to success, as with any LLM features, is measuring performance and iterating on implementations. To repeat: you should consider adding complexity only when it demonstrably improves outcomes.
这些基础组件不是必须照搬的规定,只是一些常见模式,开发者可以按自己的场景调整、组合。跟做任何 LLM 功能一样,关键在于衡量效果、不断迭代。再说一遍:只有在确实能改善结果的时候,才考虑加复杂度。
Summary总结
Success in the LLM space isn't about building the most sophisticated system. It's about building the right system for your needs. Start with simple prompts, optimize them with comprehensive evaluation, and add multi-step agentic systems only when simpler solutions fall short.
在 LLM 这个领域,做成功靠的不是把系统做得最复杂,是做一个适合自己需求的系统。从简单的提示词开始,用全面的评测去优化,只有更简单的方案确实不够用了,再加上多步骤的 Agent 系统。
When implementing agents, we try to follow three core principles:
做 Agent 时,我们尽量守住三条核心原则:
- Maintain simplicity in your agent's design.Agent 的设计保持简单。
- Prioritize transparency by explicitly showing the agent’s planning steps.把 Agent 的规划步骤明明白白展示出来,透明优先。
- Carefully craft your agent-computer interface (ACI) through thorough tool documentation and testing.靠扎实的工具文档和测试,用心打磨 Agent 和计算机之间的接口(agent-computer interface,ACI)。
Frameworks can help you get started quickly, but don't hesitate to reduce abstraction layers and build with basic components as you move to production. By following these principles, you can create agents that are not only powerful but also reliable, maintainable, and trusted by their users.
框架能帮你快速起步,但往生产环境走的时候,该砍抽象层就砍,直接用基础组件来搭,别犹豫。照着这些原则做,你做出来的 Agent 不光能力强,还可靠、好维护,用户也信得过。
Acknowledgements致谢
Written by Erik S. and Barry Zhang. This work draws upon our experiences building agents at Anthropic and the valuable insights shared by our customers, for which we're deeply grateful.
作者 Erik S. 和 Barry Zhang。本文基于我们在 Anthropic 做 Agent 的经验,以及客户分享给我们的宝贵见解,在此深表感谢。
Appendix 1: Agents in practice附录 1:Agent 实践
Our work with customers has revealed two particularly promising applications for AI agents that demonstrate the practical value of the patterns discussed above. Both applications illustrate how agents add the most value for tasks that require both conversation and action, have clear success criteria, enable feedback loops, and integrate meaningful human oversight.
跟客户合作下来,我们发现有两个 AI Agent 应用特别有前景,上面这些模式的实际价值在它们身上看得很清楚。这两个应用都表明,Agent 最能发挥价值的任务是这样的:既要对话又要动手,成功标准清楚,能形成反馈闭环,并且有真正起作用的人工监督。
A. Customer supportA. 客户支持
Customer support combines familiar chatbot interfaces with enhanced capabilities through tool integration. This is a natural fit for more open-ended agents because:
客户支持把大家熟悉的聊天机器人界面,和接入工具后获得的增强能力结合到了一起。它天然适合用更开放的 Agent 来做,因为:
- Support interactions naturally follow a conversation flow while requiring access to external information and actions;客服本来就是一来一回的对话,同时又需要查外部信息、执行操作;
- Tools can be integrated to pull customer data, order history, and knowledge base articles;可以接入工具去拉客户资料、订单历史和知识库文章;
- Actions such as issuing refunds or updating tickets can be handled programmatically; and退款、更新工单这类操作可以用程序来处理;
- Success can be clearly measured through user-defined resolutions.成没成功,可以按用户自己定义的「问题已解决」来清楚地衡量。
Several companies have demonstrated the viability of this approach through usage-based pricing models that charge only for successful resolutions, showing confidence in their agents' effectiveness.
已经有几家公司采用按用量计费、只对成功解决的问题收费的模式,证明了这条路走得通,也看得出他们对自家 Agent 的效果很有信心。
B. Coding agentsB. 编程 Agent
The software development space has shown remarkable potential for LLM features, with capabilities evolving from code completion to autonomous problem-solving. Agents are particularly effective because:
LLM 功能在软件开发领域的潜力很大,能力已经从代码补全一路发展到自主解决问题。Agent 在这里格外好用,因为:
- Code solutions are verifiable through automated tests;代码方案可以用自动化测试来验证;
- Agents can iterate on solutions using test results as feedback;Agent 可以把测试结果当反馈,反复改进方案;
- The problem space is well-defined and structured; and问题空间定义清楚、结构分明;
- Output quality can be measured objectively.输出质量可以客观衡量。
In our own implementation, agents can now solve real GitHub issues in the SWE-bench Verified benchmark based on the pull request description alone. However, whereas automated testing helps verify functionality, human review remains crucial for ensuring solutions align with broader system requirements.
在我们自己的实现里,Agent 现在只看 pull request 的描述,就能解决 SWE-bench Verified 基准里真实的 GitHub issue。不过自动化测试只能帮着验证功能,方案是否符合整个系统更大范围的要求,还是得靠人来审查。
Appendix 2: Prompt engineering your tools附录 2:为工具做提示词工程
No matter which agentic system you're building, tools will likely be an important part of your agent. Tools enable Claude to interact with external services and APIs by specifying their exact structure and definition in our API. When Claude responds, it will include a tool use block in the API response if it plans to invoke a tool. Tool definitions and specifications should be given just as much prompt engineering attention as your overall prompts. In this brief appendix, we describe how to prompt engineer your tools.
不管你做的是哪种 Agent 系统,工具多半都是 Agent 里很重要的一块。在我们的 API 里写明工具确切的结构和定义,工具就能让 Claude 跟外部服务和 API 打交道。Claude 回复时如果打算调用工具,API 响应里就会带一个 tool use block。在提示词工程上,工具的定义和说明应该得到跟整体提示词一样多的关注。这篇附录就简单讲讲怎么给工具做提示词工程。
There are often several ways to specify the same action. For instance, you can specify a file edit by writing a diff, or by rewriting the entire file. For structured output, you can return code inside markdown or inside JSON. In software engineering, differences like these are cosmetic and can be converted losslessly from one to the other. However, some formats are much more difficult for an LLM to write than others. Writing a diff requires knowing how many lines are changing in the chunk header before the new code is written. Writing code inside JSON (compared to markdown) requires extra escaping of newlines and quotes.
同一个操作往往有好几种表达方式。比如编辑文件,可以写一个 diff,也可以把整个文件重写一遍;结构化输出,可以把代码放在 markdown 里返回,也可以放在 JSON 里。在软件工程里,这些差别只是表面上的,彼此可以无损转换。但对 LLM 来说,有些格式比别的难写得多。写 diff 时,还没写新代码,就得先在块头里写明要改多少行。把代码写进 JSON(跟 markdown 比)还得额外转义换行和引号。
Our suggestions for deciding on tool formats are the following:
挑工具格式时,我们的建议是:
- Give the model enough tokens to "think" before it writes itself into a corner.给模型留够 token 去「想」,别让它写着写着把自己逼进死角。
- Keep the format close to what the model has seen naturally occurring in text on the internet.格式尽量贴近模型在互联网文本里自然见过的样子。
- Make sure there's no formatting "overhead" such as having to keep an accurate count of thousands of lines of code, or string-escaping any code it writes.别让格式带来额外「负担」,比如要准确数清几千行代码,或者写的每段代码都要做字符串转义。
One rule of thumb is to think about how much effort goes into human-computer interfaces (HCI), and plan to invest just as much effort in creating good agent -computer interfaces (ACI). Here are some thoughts on how to do so:
有条经验法则:想想大家在人机交互界面(HCI)上花了多少心思,就准备在做好 Agent-计算机接口(ACI)上花同样多的心思。具体怎么做,有这么几点想法:
- Put yourself in the model's shoes. Is it obvious how to use this tool, based on the description and parameters, or would you need to think carefully about it? If so, then it’s probably also true for the model. A good tool definition often includes example usage, edge cases, input format requirements, and clear boundaries from other tools.站在模型的角度想一想。光看描述和参数,这个工具怎么用一目了然吗,还是得仔细琢磨?要是你都得琢磨,模型多半也一样。好的工具定义通常会写上用法示例、边界情况、输入格式要求,以及跟其他工具的清楚界限。
- How can you change parameter names or descriptions to make things more obvious? Think of this as writing a great docstring for a junior developer on your team. This is especially important when using many similar tools.参数名或描述怎么改,才能让意思更明显?就当是给团队里的新人写一份好的 docstring。同时用到很多相似工具的时候,这一点尤其重要。
- Test how the model uses your tools: Run many example inputs in our workbench to see what mistakes the model makes, and iterate.测试模型怎么用你的工具:在我们的 workbench 里跑大量示例输入,看模型会犯哪些错,然后迭代。
- Poka-yoke your tools. Change the arguments so that it is harder to make mistakes.给工具做防呆设计(Poka-yoke):改一改参数,让它更难用错。
While building our agent for SWE-bench, we actually spent more time optimizing our tools than the overall prompt. For example, we found that the model would make mistakes with tools using relative filepaths after the agent had moved out of the root directory. To fix this, we changed the tool to always require absolute filepaths—and we found that the model used this method flawlessly.
给 SWE-bench 做 Agent 的时候,我们花在优化工具上的时间,其实比优化整体提示词还多。比如我们发现,Agent 离开根目录之后,模型在用相对路径的工具上就会出错。为了解决这个问题,我们把工具改成一律要求绝对路径,结果模型用起来一次错都没出。